📘Overview
Updated July 3, 2026Cloud and platform operations is the discipline of running software reliably and efficiently on modern infrastructure — Kubernetes clusters, multi-cloud environments, and the pipelines that deliver code to them. It is where two relentless pressures meet: keeping systems reliable, and controlling cloud spend that can balloon without constant tuning. Rightsizing workloads, optimizing clusters, managing infrastructure-as-code, and catching configuration drift are painstaking, never-finished tasks — a natural fit for autonomous AI.
💡The AI Opportunity
AI here increasingly takes action, not just gives advice. Autonomous optimization engines continuously rightsize compute, scale nodes, and shift to cheaper capacity while protecting performance; agentic infrastructure-as-code tools generate and reconcile configuration against live cloud reality; and AI site-reliability agents troubleshoot Kubernetes and remediate issues. This is closely related to the DevOps and platform-engineering work of shipping software, but the emphasis is on operating what's already running — cost, reliability, and scale — rather than building it.
🤖AI in Action
Autonomous Kubernetes and cloud optimization is led by Cast AI, ScaleOps, and Sedai, whose engines rightsize and self-heal in real time to cut cost (Sedai extends to GPU and AI-workload tuning). Komodor provides an AI site-reliability agent for Kubernetes troubleshooting, Firefly brings agentic AI to infrastructure-as-code by codifying live cloud and fighting drift, and Harness runs specialized agents across the software-delivery pipeline. Port turns the internal developer portal into an agentic platform-engineering hub, and NVIDIA Run:ai orchestrates GPU clusters for AI compute.
📊Impact on Jobs
AI is turning cloud and platform operations from constant manual tuning into a largely self-driving discipline, which matters as Kubernetes complexity and cloud (and GPU) costs climb. The work shifts from hand-tuning resources toward setting guardrails and supervising autonomous optimization, raising the value of platform engineers who understand both infrastructure and the AI managing it. This cluster overlaps the DevOps and platform-engineering craft of building software, but centers on running it efficiently at scale. The honest caveat is trust: teams adopt autonomous cost optimization readily, but stay cautious about fully autonomous production changes — so the strongest tools pair automation with safety guarantees and clear guardrails.
Keep track of the topics you follow
- Save the topics you follow
- Get ⚡ alerts when their tools and companies change
- Curated tools for this topic, from 900+ AI tool profiles
- Today’s top AI Stories — the day’s most important AI news, free
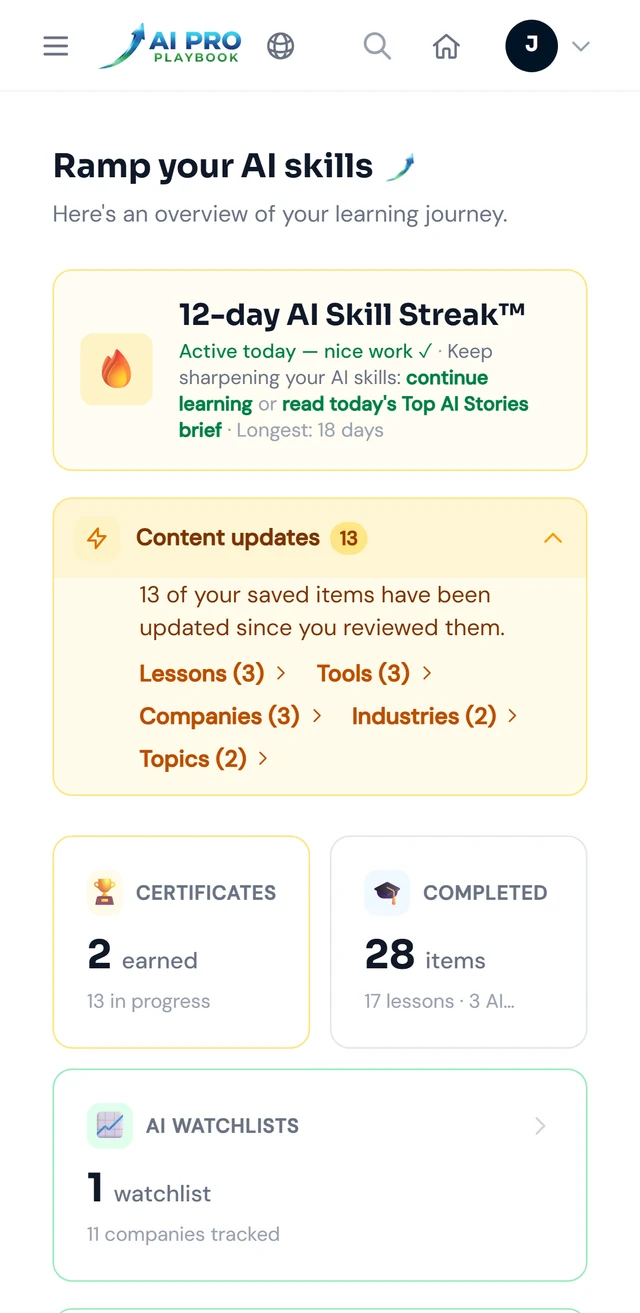
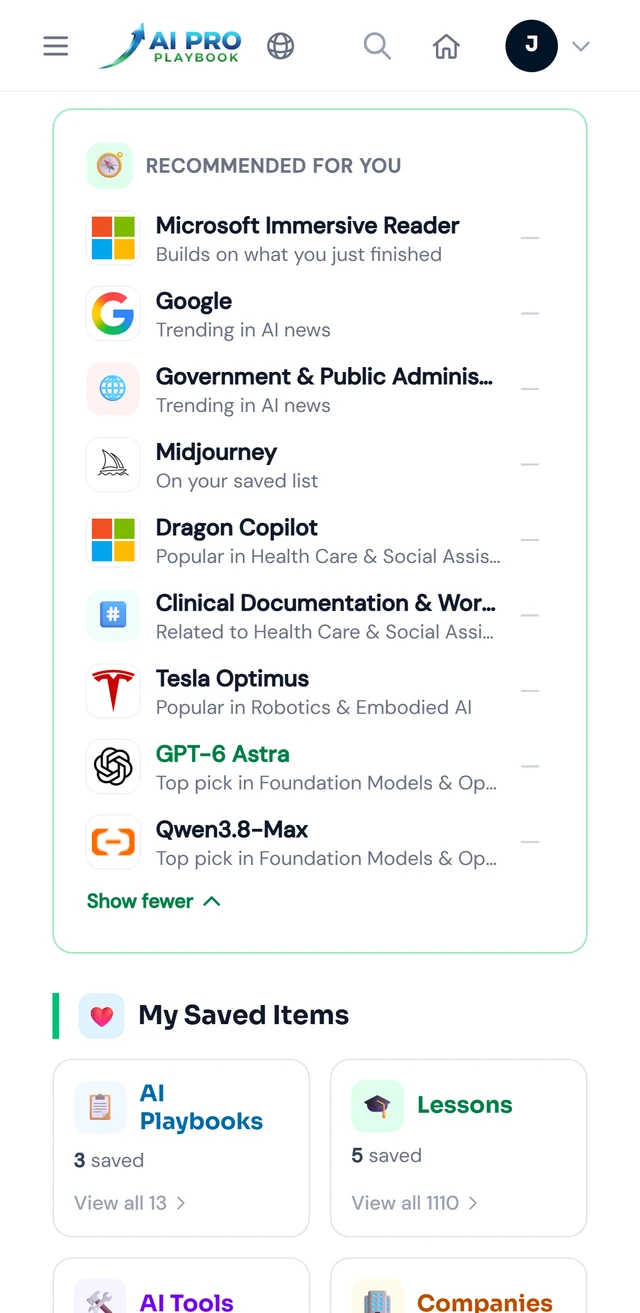
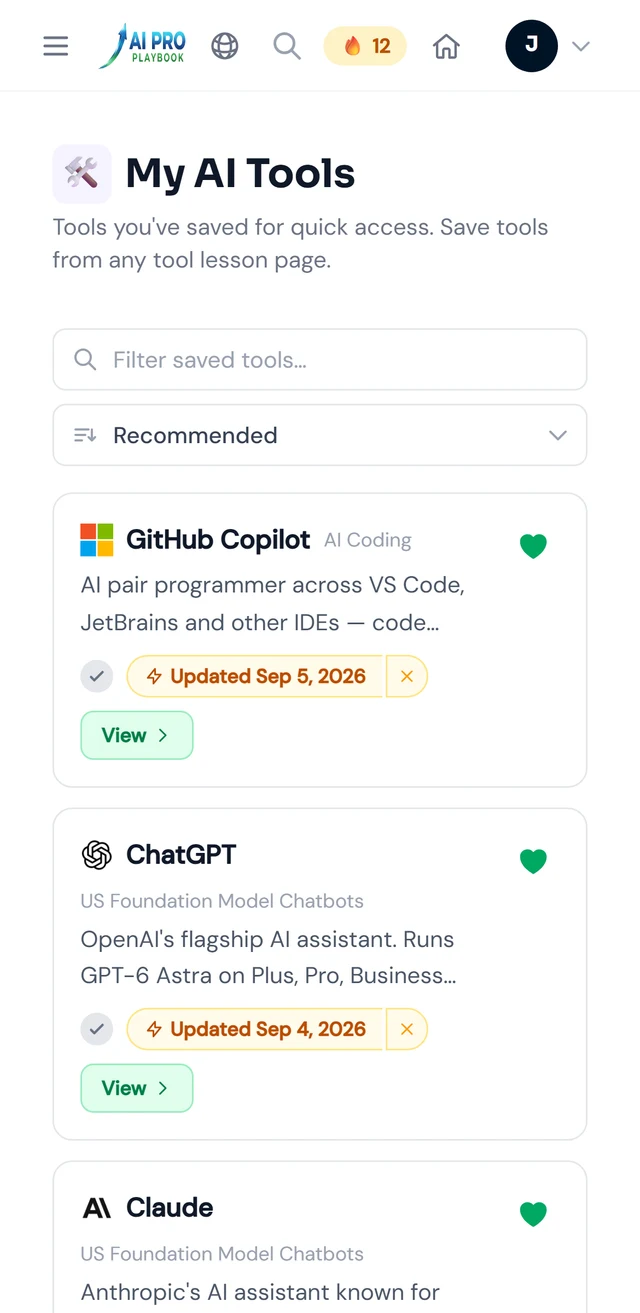
Swipe for Recommended for you and My AI Tools
Your AI Hub — sample data. See desktop view example
🛠️Top AI Tools for This Topic
 Harness AI
AI-native software delivery with specialized agents across CI/CD, cloud cost, and ops.

Managed platform from the creators of Ray, the open-source engine for distributing AI workloads across thousands of GPUs — data processing, training, tuning, batch inference and serving on one shared resource pool.
 Nscale Cloud
British neocloud running its own AI data centers across Norway, the UK and the US, with on-demand GPU instances, managed Slurm and Kubernetes, fine-tuning and inference endpoints. Filed to list on the NYSE in September 2026; the filing shows more than $103 billion in contracted backlog, about 85 percent of it from just two customers, Microsoft and Anthropic.